
OpenAI speech provider
An OpenAI speech provider lets Live Hub use your OpenAI account for text-to-speech (TTS), speech-to-text (STT), or both.
OpenAI's advanced configuration parameters can be set at either of two levels:
- Provider level: Enter the parameters in the 'Provider configuration' field. A parameter set on the provider applies to every bot connection that uses the provider.
- Bot connection level: Enter the parameters on the bot connection's Advanced tab. A parameter set on a bot connection applies to that connection only.
If the same parameter is set at both levels, the bot connection value takes precedence.
Add an OpenAI speech provider
To add an OpenAI speech provider:
-
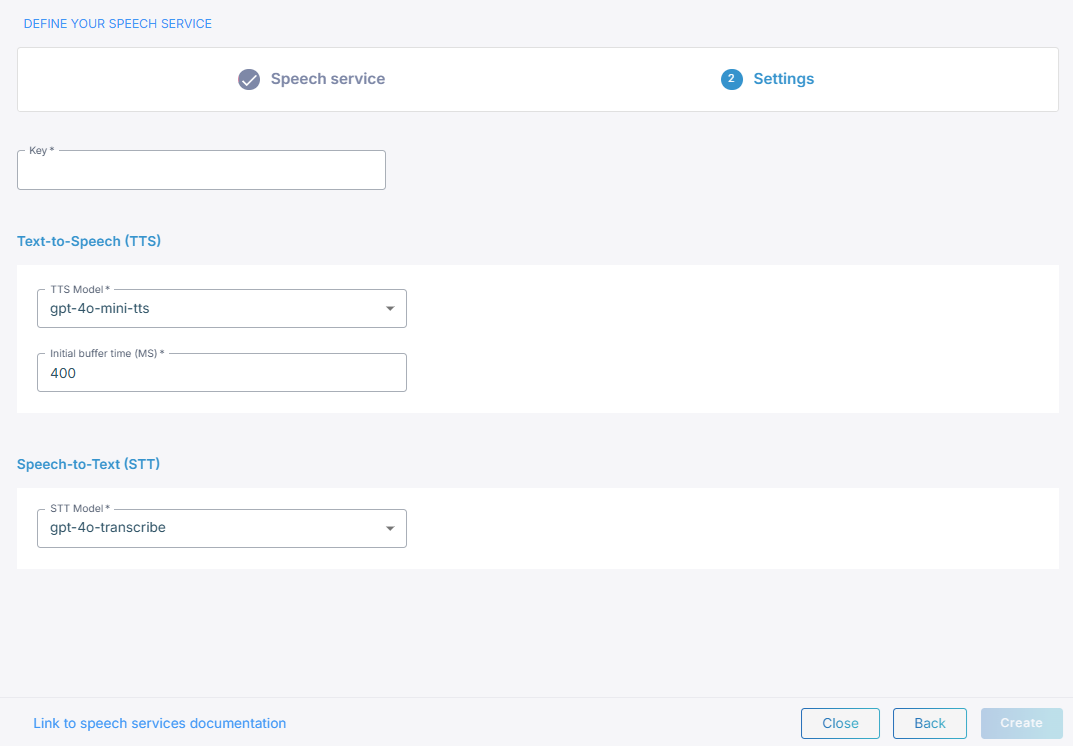
In the 'Authentication key' field, enter your OpenAI API key.
-
From the 'TTS Model' drop-down list, select gpt-4o-mini-tts.
-
From the 'STT Model' drop-down list, select whisper-1, gpt-4o-transcribe, gpt-4o-mini-transcribe, or gpt-realtime-1.5.
-
Optional: Under Advanced, in the 'Provider configuration' field, enter the advanced configuration parameters that apply to every bot connection using this provider, such as
playInitialBufferTimeMSto buffer audio before playing it to the caller and absorb the model's start-up delay. See Configure advanced parameters at the provider level. -
Click Create.
Configure advanced parameters at the provider level
The JSON you enter in 'Provider configuration' is merged into every request Live Hub sends to OpenAI, so it applies to every bot connection using this provider.
Configure advanced parameters at the bot connection level
Synthesis parameters go under ttsPassthruConfig in the JSON editor on the bot
connection's Advanced tab, and Live Hub merges them into the request it sends to
OpenAI. See Manage bot connections.
The full set of text-to-speech parameters is Create Speech in OpenAI's audio API documentation.
{
    "ttsPassthruConfig": {
        "speed": 1.25
    }
}
Setting model here overrides the 'TTS Model' drop-down list on the provider.
Set the speaking style
ttsInstructions tells the model how to speak. It goes on the same Advanced tab,
alongside ttsPassthruConfig rather than inside it:
{
    "ttsInstructions": "Speak in a cheerful and positive tone."
}
Tune recognition
Recognition parameters go under sttPassthruConfig on the same tab. Live Hub sends them
in the session it opens with OpenAI's realtime API, so they take the shape that API
defines:
{
    "sttPassthruConfig": {
        "audio": {
            "input": {
                "noise_reduction": {
                    "type": "near_field"
                }
            }
        }
    }
}
Turn-taking
Live Hub ends the caller's turn after a period of silence. One field on the bot connection's Settings tab, under Speech-to-Text (STT) Settings, sets how long Live Hub waits. The field has a bot parameter behind it, which you can set on the Advanced tab instead:
| Field | Bot parameter |
|---|---|
| 'End-of-turn timeout (ms)' | sttSegmentationSilenceTimeoutMs
|
The default is 800 ms, and the range is from 100 to 5000 ms. If the timeout is too short, Live Hub ends the turn while the caller is still speaking. If the timeout is too long, the bot waits after the caller has finished.
Language and voice
You select the language and the voice per bot connection, on its Settings tab, not on the provider. See Manage bot connections.